Create
Release-by-release coverage of the AI creation stack: video, image, music, voice, design and code generation tools.
Release-by-release coverage of the AI creation stack: video, image, music, voice, design and code generation tools.
Latest in Create
30 stories
Microsoft's Copilot Cowork moves to usage-based billing and may tap DeepSeek
Microsoft is weighing a fine-tuned version of Deepseek V4 as a cheaper model option for Copilot Cowork. The company is also switching to usage-based billing, si…

SpaceX bets $60 billion on Cursor to catch OpenAI and Anthropic
Just two trading days after its IPO, Elon Musk's SpaceX is buying AI coding startup Anysphere. The deal is meant to help the struggling xAI division catch up wi…

Microsoft Research's Mirage gives video generation a persistent spatial memory that doesn't forget what's around the corner
Mirage, a video world model from Microsoft Research and several universities, stores scene information directly in latent space instead of pixel-based point clo…

Announcing Ironwood TPUs General Availability and new Axion VMs to power the age of inference
Today’s frontier models, including Google’s Gemini, Veo, Imagen, and Anthropic’s Claude train and serve on Tensor Processing Units (TPUs). For many organization…

Apply AI Webinar on AI for Cultural, Creative and Media Sectors
Apply AI Webinar on AI for Cultural, Creative and Media Sectors Anonymous (not verified) Tue, 06/02/2026 - 12:29 24 June 2026 This webinar will focus on …

Nano Banana 2 and Nano Banana Pro are generally available, and already powering creative workflows
Organizations are unlocking entirely new ways to use image generation and editing across their industries. To drive next-generation experiences, businesses are …

Developer's guide to Gemini Enterprise and A2UI integration
If you've built a chatbot, you know this conversation: User: "Book a table for two tomorrow at 7pm." Agent: "Okay, for what day?" User: "Tomorrow." Agent: "What…

Doubling Down on Suno, the Platform for Creative Entertainment
Every major consumer platform is built on a new behavior. TikTok made short-form video consumption mainstream. Netflix changed how we watch TV. Suno is doing so…
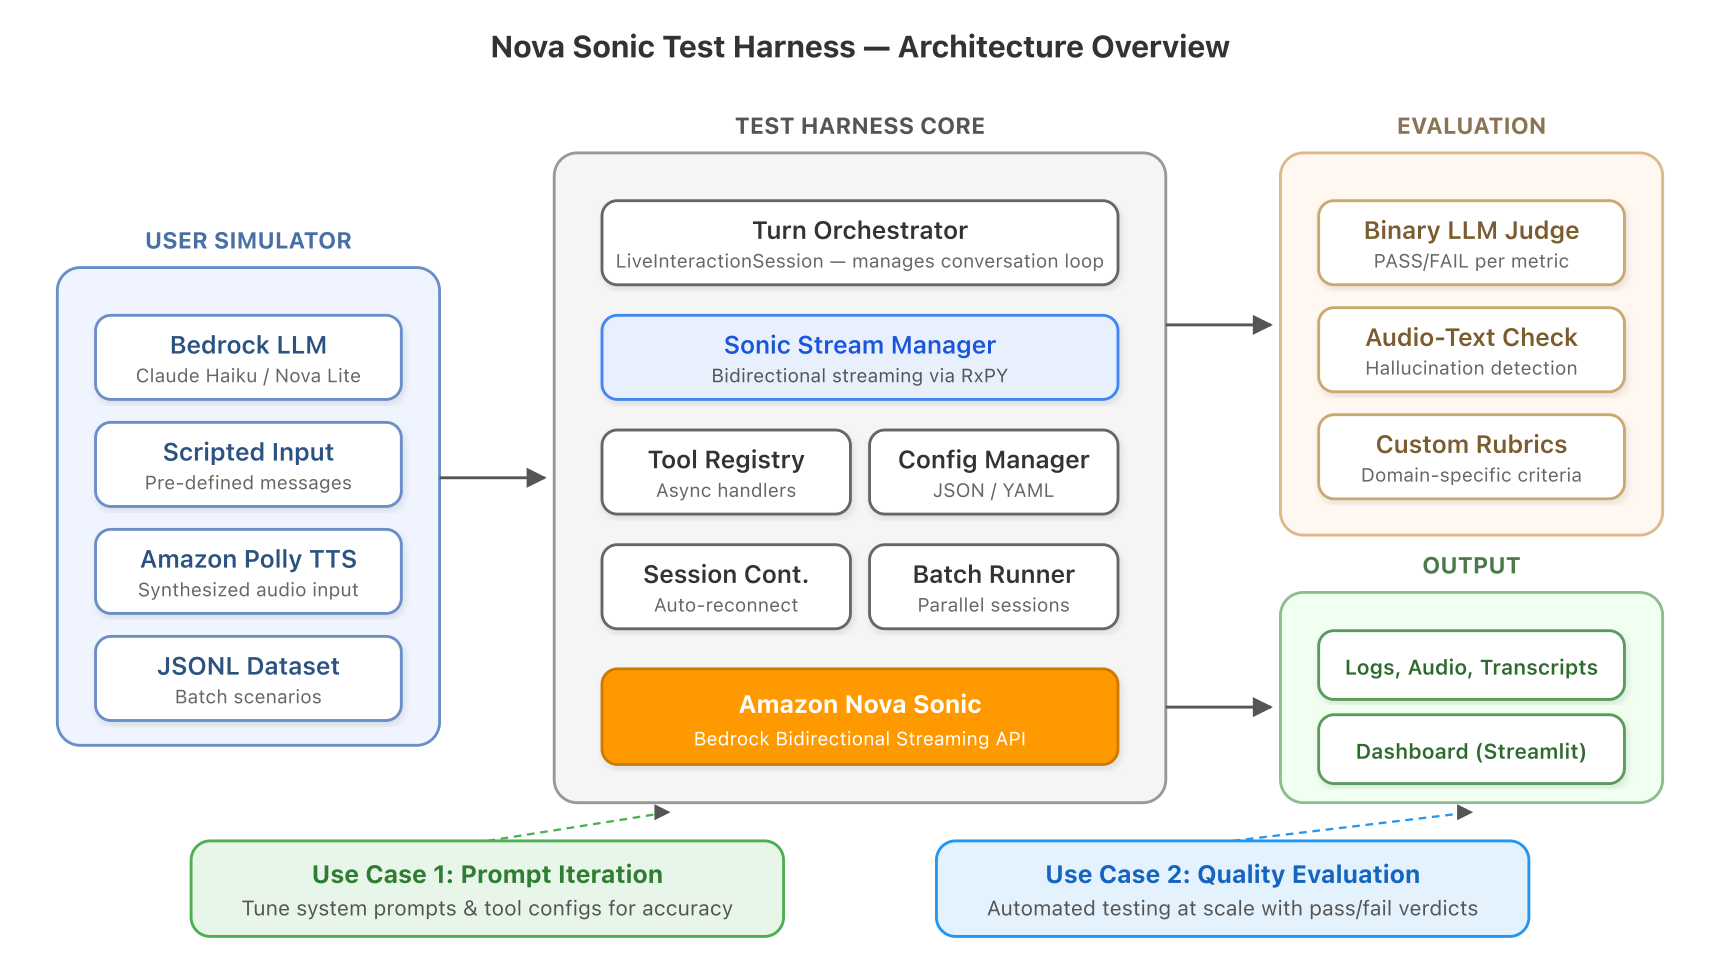
Evaluate your Amazon Nova Sonic voice agent at scale, no microphone required
In this post, we walk you through the Nova Sonic Test Harness, an open source framework that we built to solve both problems. It serves as a rapid iteration too…
Modernizing Healthcare: How Alcidion achieved greater stability and performance with AlloyDB
In clinical informatics, every second counts. For Alcidion, a global leader in smart health solutions, the mission is simple but critical: use technology to red…
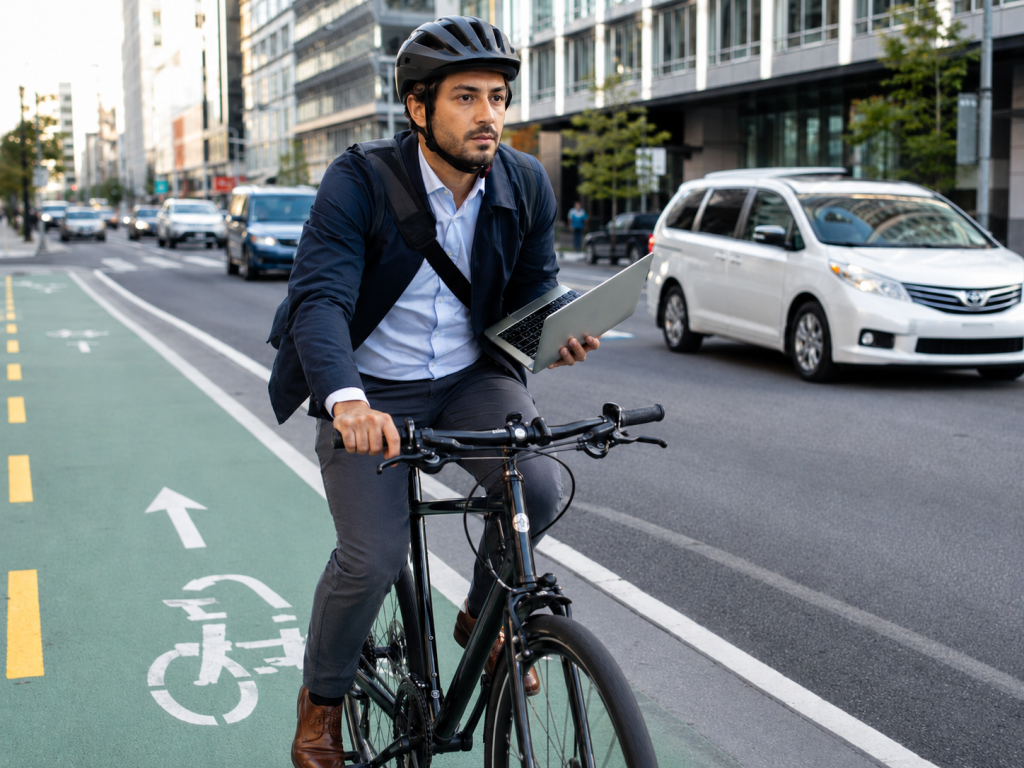
It’s safe to close your laptop now: Hosting coding agents on Amazon Bedrock AgentCore
Amazon Bedrock AgentCore Runtime gives each agent session its own isolated microVM with a persistent workspace, secure tool access through Gateway, and built-in…

MCP Apps - Bringing UI Capabilities To MCP Clients
MCP Apps is now live as the first official MCP extension — tools can return interactive UI components that render directly in the conversation.…

Whole-Body Conditioned Egocentric Video Prediction
.modal { display: none; position: fixed; z-index: 9999; padding-top: 50px; left: 0; top: 0; width: 100%; height: 100%; overflow: auto; background-color: rgba(0,…

GridSFM: A new, small foundation model for the electric grid
Introducing GridSFM, a small foundation model that can predict AC optimal power flow in milliseconds, boosting efficiency and unlocking cost savings. Learn how …
TetherCache: Stabilizing Autoregressive Long-Form Video Generation with Gated Recall and Trusted Alignment
Autoregressive video diffusion models provide a natural formulation for streaming and variable-length video generation by conditioning newly generated frames on…
Limits of spectral learning under noise
Learning functional relationships from noisy data is a central problem in scientific inference. Spectral methods approximate unknown functions by expanding them…
DuET: Dual Expert Trajectories for Diffusion Image Editing
Recent diffusion editors perform diverse instruction-based edits while conditioning on the source image at every denoising step. Yet persistent source-image con…
Adaptive Turn-Taking for Real-time Multi-Party Voice Agents
Turn-taking in multi-party spoken conversations remains a fundamental challenge for voice-based agents, particularly under dynamic floor competition and varying…
Modality Forcing for Scalable Spatial Generation
Text-to-image (T2I) models contain rich spatial priors. Synthesizing photorealistic, cluttered scenes requires an understanding of geometry, including perspecti…
InterleaveThinker: Reinforcing Agentic Interleaved Generation
Recent image generators have demonstrated impressive photorealism and instruction-following capabilities in single-image generation and editing. However, constr…

A new way to express yourself: Gemini can now create music
The Gemini app now features our most advanced music generation model Lyria 3, empowering anyone to make 30-second tracks using text or images.…

OpenAI Codex and Figma launch seamless code-to-design experience
OpenAI and Figma launch a new Codex integration that connects code and design, enabling teams to move between implementation and the Figma canvas to iterate and…

Nano Banana 2: Combining Pro capabilities with lightning-fast speed
Our latest image generation model offers advanced world knowledge, production ready specs, subject consistency and more, all at Flash speed.…

Creating with Sora Safely
To address the novel safety challenges posed by a state-of-the-art video model as well as a new social creation platform, we’ve built Sora 2 and the Sora app wi…
Speaking of Voxtral
Voxtral TTS: A frontier, open-weights text-to-speech model that’s fast, instantly adaptable, and produces lifelike speech for voice agents.…

Gemini 3.1 Flash Live: Making audio AI more natural and reliable
Our latest voice model has improved precision and lower latency to make voice interactions more fluid, natural and precise.…
Codex for (almost) everything
The updated Codex app for macOS and Windows adds computer use, in-app browsing, image generation, memory, and plugins to accelerate developer workflows.…
Introducing ChatGPT Images 2.0
ChatGPT Images 2.0 introduces a state-of-the-art image generation model with improved text rendering, multilingual support, and advanced visual reasoning.…
Uber uses OpenAI to help people earn smarter and book faster
Uber uses OpenAI to power AI assistants and voice features that help drivers earn smarter and riders book faster across a global real-time marketplace.…
Advancing voice intelligence with new models in the API
Explore new realtime voice models in the OpenAI API that can reason, translate, and transcribe speech, enabling more natural and intelligent voice experiences.…